Eigenvectors, eigenvalues - Part II
The example above illustrates a general fact: if a matrix has enough independent eigenvectors to form a basis of the vector space on which acts, then if you write in the basis of these eigenvectors, it will have a diagonal form.
In other words, the eigenbasis of is a natural basis for . It is a basis in which the action of is extremely simple: it is given by scaling the basis vectors by the respective eigenvalue numbers.
Sometimes a matrix has not enough independent eigenvectors. Here is an illustration:
Eigenvectors, eigenvalues - Part II (part 2)
Sometimes a real matrix has complex eigenvalues and eigenvectors. Here is an illustration:
Eigenvectors, eigenvalues - Part II (part 3)
It is important to be aware of these two situations. For the sake of exams, you should memorize one example of each type. (You can use the two above.)
Eigenvectors, eigenvalues - Part II (part 4)
Spectral Theorem: symmetric matrices have good eigen theory
A key point of the Spectral Theorem is that symmetric matrices never encounter the phenomena illustrated in the two examples above. Eigenvalues are always real numbers, and there are always enough eigenvectors to form a basis.
Eigenvectors vs. singular vectors
It is helpful to think about the concept of an eigenvector as consisting of two aspects:
- (1) Matrix acting by scaling
- (2) Fixed lines of matrix action
Aspect (1) allows easy computation and geometric understanding of the matrix action. It also allows us to focus on vectors that are more important (those having a larger scale factor). If we have a basis of such vectors, the matrix will have a simple diagonal form when written in this basis.
Aspect (2) goes much further, even though it essentially includes aspect (1). A fixed line (eigenline) is the span of any eigenvector. Such lines are mapped to themselves by the matrix action. This aspect describes eigenvector spans as analogues of fixed points of a function. The concept of fixed points and fixed lines (‘fixity’ in general) only applies when the function or matrix keeps vectors in the same space, i.e. has the same codomain as domain.
Eigenvectors
There are various contexts where a matrix does act on vectors in a single space. Aspect (2) is very useful in these contexts. For example, a differential operator, which produces a system of first-order linear differential equations, involves a matrix for a vector space of functions . For another example, the moment of inertia matrix describing angular moment of D bodies in physics. Or the many operators of quantum mechanics.
One of the biggest advantages of aspect (2) is that it is compatible with iteration.
If is a linear transformation (i.e. a matrix) having the same codomain as domain, we can define iterates etc. as matrix powers. These powers allow one to apply functions to matrices: if is a power series, we can define by the power series . (Bracketing any problems with convergence.) An extremely important series is , since the function solves the linear ODE system .
It is hard to compute , or more generally , by direct multiplication and limits of partial sums. On the other hand, it is easy to compute when is a diagonal matrix, just as it is easy to compute when is an eigenvector of . (Namely, the latter is .) For example, in the case we have .
Even when is not diagonal, if an eigenbasis matrix can be found, then the powers of are still easy to calculate, because (e.g. in D):
Similarly we have:
The critical piece of the calculation above is the cancellation occurring in the calculation for . This cancellation shows that matrix multiplication and change of basis can be performed in either order. That in turn means we can first change basis to an eigenbasis (if it exists) and then perform multiplication with the diagonal matrices where it is easy, and only afterwards change back to the standard basis.
Singular vectors
The concept of singular vector is designed to make use of aspect (1) of eigenvectors without aspect (2). Because they do not include aspect (2), singular vectors of are not eigenvectors of except in special cases. They do not determine fixed lines of the action.
Unlike eigenvectors and eigenvalues, singular vectors and singular values are (best) defined in the context of a collection of vectors giving the singular value decomposition (SVD). So, a singular vector is one of the vectors in the SVD.
Defining the singular value decomposition
Suppose is a matrix providing a linear transformation between different vector spaces.
SVD features
A singular value decomposition of is given by: where:
- is an orthogonal matrix giving a rotation/reflection combo for (input)
- is an orthogonal matrix giving a rotation/reflection combo for (output)
- has non-negative entries on the main diagonal (possibly zeros!) and zeros elsewhere. (Here .) It is not square if . It could look like these, for example:
The orthonormal basis vectors are called right singular vectors.
The orthonormal basis vectors are called left singular vectors.
The values are the lengths of the images, namely .
(Remember: “Right Input, Left Output.”)
An alternate way to write the SVD uses scalar projections attached to the vectors :
Each term takes an input vector, dots it with , then applies this value to scaled by . With this formula, we can compute for any input using dot products:
By plugging in , we verify that and , etc. up to . (For , we have .)
Singular vectors vs. eigenvectors
The rule looks analogous to the rule for eigenvectors.
But it’s actually very different! Notice that and are not even vectors in the same space!
The rule does not by itself determine any special property of or . (Take any unit vector , apply , then define and .)
The significance of the rule manifests when it holds simultaneously on all vector pairs in orthonormal bases and .
Still, the SVD says that after rotating / reflecting the basis of and the basis of by suitable orthogonal matrices (not necessarily the same on each), the action of can be represented as simple scalings by .
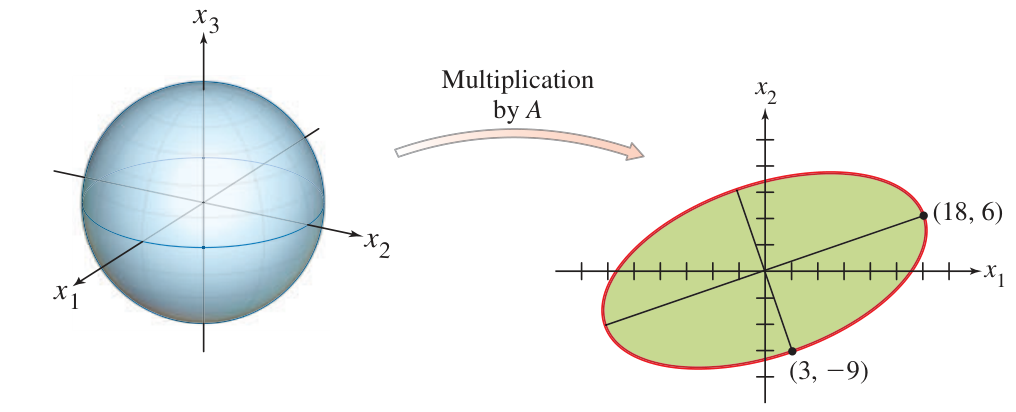
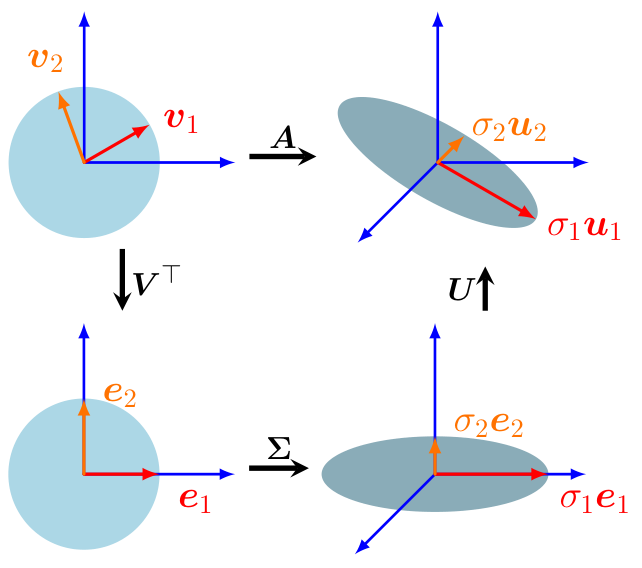
We may think of as a special basis for the input space vis-à-vis the matrix , and as a corresponding basis for the output space . Then acts by pairing the vector to and stretching it by .
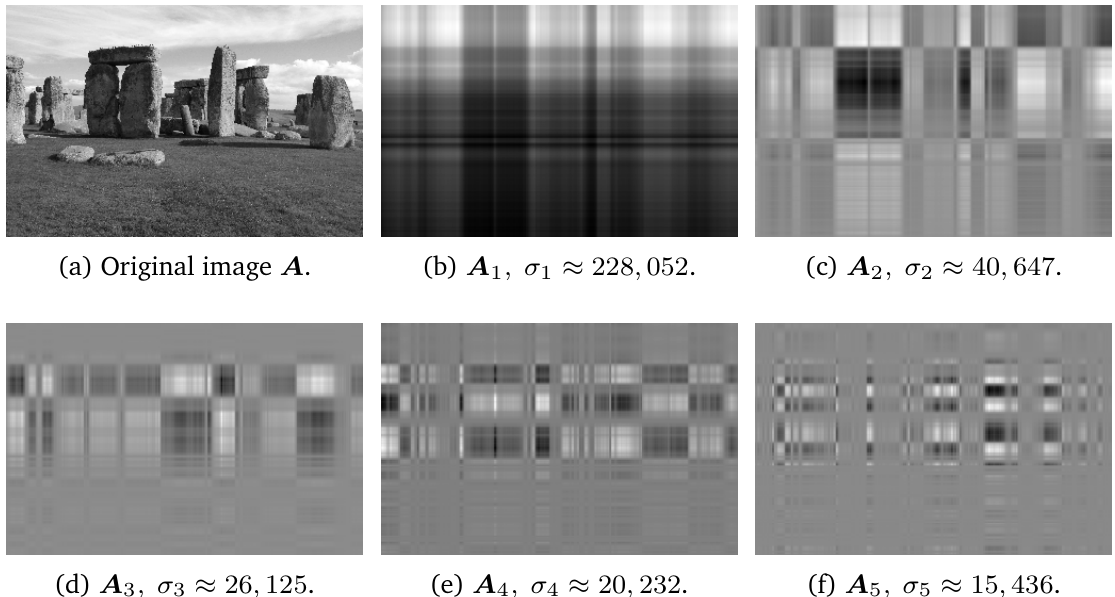
Partial matrices for .
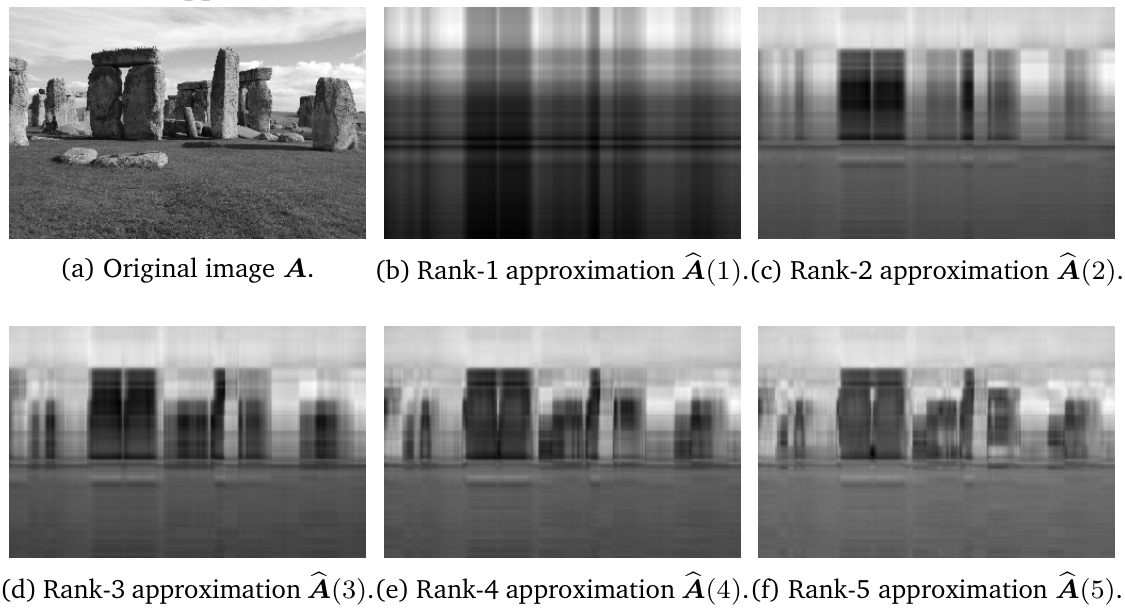
Partial sum matrices for .
Computing the singular value decomposition
In practice, on a computer, the SVD is calculated using numerical procedures that are akin to those used to find approximations to eigenvectors. We do not address those kinds of procedures in this course.
Still, it is possible to specify and calculate SVD elements by hand for a matrix by making use of the fact that is always a symmetric matrix and the Spectral Theorem can be applied to it. This method also shows that the SVD always exists, since the symmetric always has real eigenvalues and enough eigenvectors by the Spectral Theorem, even when does not. Let us see how this works.
First observe that , so is always symmetric. Also notice that , so the input and output spaces of this matrix are the same.
SVD elements
- orthonormal eigenbasis of .
As guaranteed by the Spectral Theorem, so here is in the notation of that theorem.- defined for .
If , then .- The equation for defines unit vectors for those with .
- Gram-Schmidt provides additional vectors when .
Computing the singular value decomposition (part 2)
Explaining the SVD elements
First, why is an orthogonal matrix?
Answer: Since is an orthonormal basis, the matrix is orthogonal.
Second, why is an orthogonal matrix?
Answer: Consider the calculation:Notes: The first line is the dot product using ‘inner product’ notation. The second line is the transpose rule. The fourth line is the definition of as eigenvector of . The last line is the property that are orthonormal vectors.
From this calculation it follows that are orthogonal vectors (at least when they aren’t zero). Since are the same vectors renormalized as unit vectors, we know are orthonormal (at least when ). In the case of , the alternate definition of using Gram-Schmidt implies that all are orthonormal.
Third, why is ?
Answer: According to the calculation above, . But by definition.Fourth, why is , with these definitions of ?
Answer: To verify the equality , it is sufficient to verify that the matrices on both sides have the same action on a basis of . (If that is true, then by linearity the matrices have the same action on any vector, and therefore they are the same matrices.)Therefore, it is sufficient to verify the equality of actions on the basis . Since this basis is orthonormal, we see that is the vector with in the row and zeros elsewhere. Then is the column of , which has in the row and zeros elsewhere. Finally is the row of (which is ) scaled by . Therefore , and this is equal to . All these statements are valid for . For , both sides send to .
Backwards: Going from SVD to eigenvectors-eigenvalues of
Addendum. If we already have an SVD given by , with on the diagonal of , then must be the eigenvectors of , and are the corresponding eigenvalues.
Proof: Observe that
where is the square diagonal matrix with diagonal entries given by . Applying the matrix to returns , which verifies the claim. (Again both matrices send to for .)